SEPIA — Changelog & Decision Log
SEPIA — Changelog & Decision Log
Reverse-chronological log of what was done, found, and decided, with dates, so anyone picking this up cold has the full context. Companion to plan.md (the forward-looking roadmap). Append new entries at the top; don't rewrite history.
Legend: DONE = action taken · FOUND = finding/evidence · DECIDED = decision made · OPEN = unresolved.
2026-07-24 — Archaic projection (WG + pigmentation) + gene-region test → the "archaics with Africans" is ascertainment/selection, not ancestry
- DONE (projection method): modern-PCA-then-project-archaics for both the whole genome and pigmentation. Installed newer plink2 (
tools/plink2, v2.0.0-a.7, gitignored) — the 2019 module can't emit PCA loadings. Recipe: modern--pca allele-wts+ archaic--score no-mean-imputation variance-standardize --read-freq, on one combined moderns+archaics bed (consistent alleles). Modern self-projection validates r = 1.code/project_archaics.slurm; coords inoutput/projections/. Workbook:archaic_projection.qmd(live, navbar "Projection"). - DONE (gene-region, B6/B7): same recipe on all variation across the 1,004-gene pigmentation-gene regions (gene body ±10 kb, ~17.5k pruned unascertained variants). Foundation
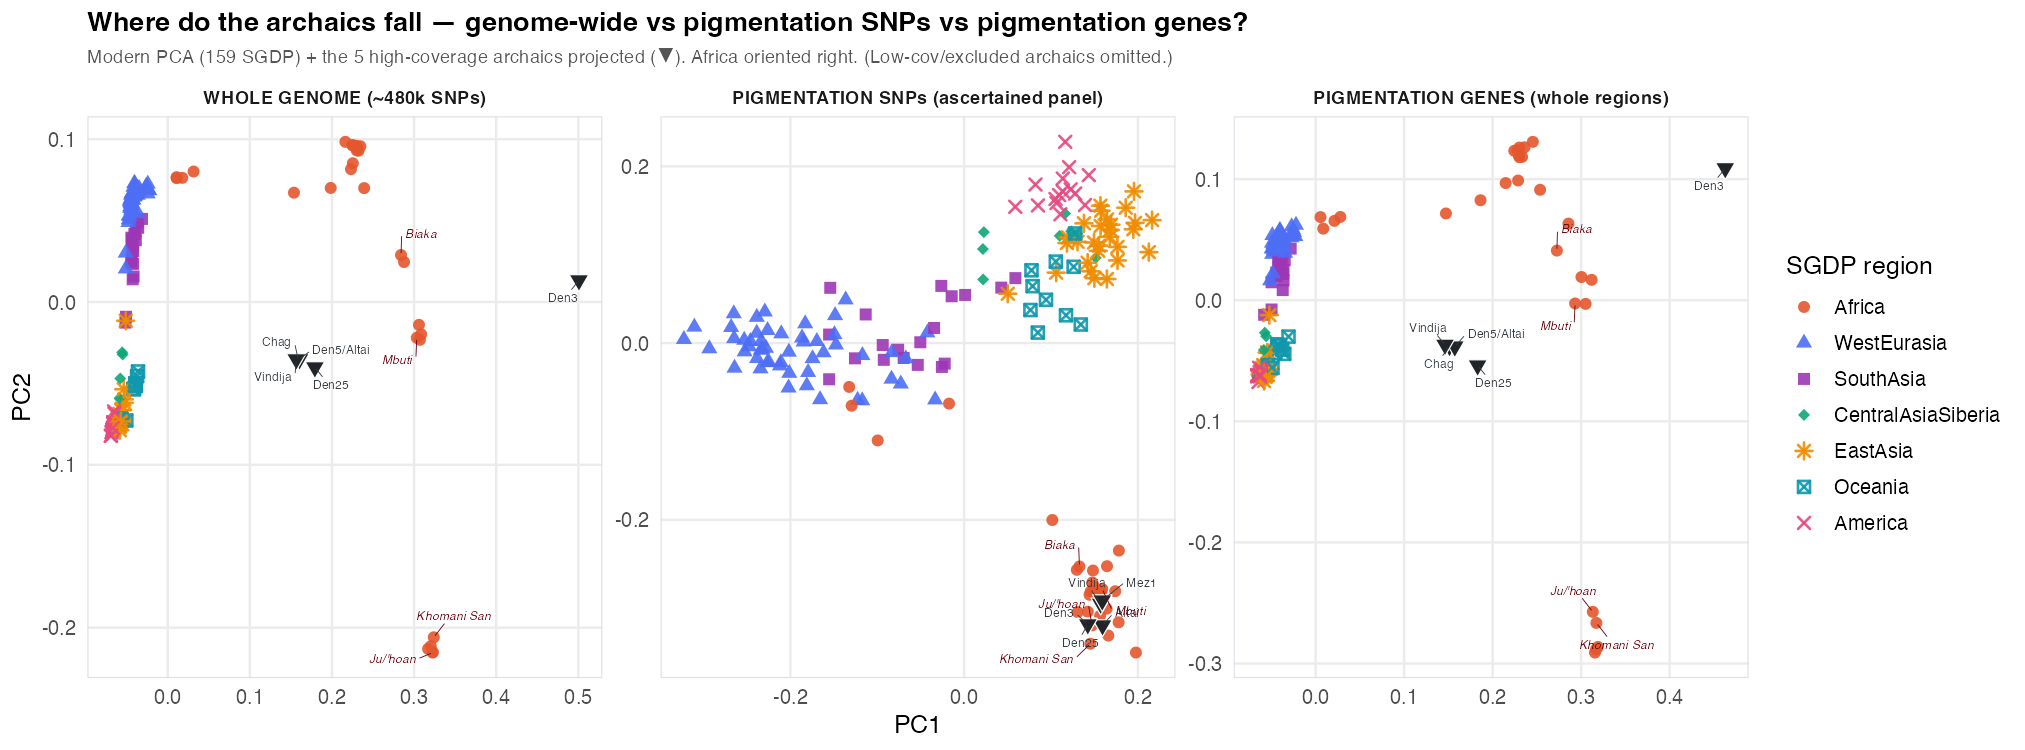
data/pigment_gene_map.tsv(Ensembl gene coords, both builds); jobcode/gene_region_pca.slurm; coordsoutput/pca_generegion/. - FINDING (key): the whole-genome and pigmentation-gene-region panels are near-identical — archaics project as a divergent outgroup at the non-African edge (high-cov PC1 ≈ 0.15). Only the ascertained pigmentation-SNP panel places archaics with Africans. ⇒ genes = ancestry, ascertained SNPs = selection: the "archaics with Africans" is the footprint of selection at derived (out-of-Africa light-skin) loci, not a pigmentation-gene ancestry signal — read as shared ancestral alleles, not phenotype/ancestry. Three-way figure:
plan/figures/three_way_projection.png. - NOTES: El Sidrón (exome-only, excluded) projects ~8× past the modern range (coverage artifact). Deep-lineage African outliers = Ju/'hoan, Khomani San (KhoeSan) + Mbuti, Biaka (rainforest HG); North Africans (Mozabite/Saharawi) nearest the non-Africans. One sample
LP6005441-DNA_A09= "unknown" (missing fromsgdp_metadata.tsv— metadata gap). Acquisition job COMPLETED (12 BAM files, ~29 GB) → unblocks ANGSD GLs + mapDamage (Q7/Q8). - Projection lessons (all fixed in the scripts): allele coding must be a single combined bed; archaic
ALT='.'collapses to duplicate IDs (--rm-dup+norm -d exact);--scoresign is flipped vs--pca(take moderns from their--scoreself-projection); split moderns/archaics by explicit name list, not/^LP/;-Tstreams (no index) where-Rneeds one;--mac 1drops monomorphic beforevariance-standardize.
2026-07-24 — Gene-network integration (B1): extended 1,155-SNP map + documented SNP-set page; wider PCA (B3) running
- DECIDED (TL): fold in everything SNP-level (GWAS Catalog + HIrisPlex-S + Martin2017 + Kim2024 + discordance); defer the gene-level tables (Bajpai/Baxter/Raghunath/D'Arcy → B6/B7); do the wider PCA first; and tag high vs low confidence (the GWAS pull mixes replicated + unreplicated hits).
- DONE (B1) —
data/pigment_snp_map.tsv(built bycode/build_pigment_snp_map.py, reproducible): 1,155 unique rsIDs unioned from all the above, each re-resolved to verified hg38 + hg19 + ref/alt via Ensembl (both tracers exact — SLC24A548134287/48426484, HERC228120472/28365618). Strict superset of the 222 panel (222 in-panel + 933 new). Confidence: 453 high / 60 moderate / 642 low (single unreplicated GWAS). Flags: 213 palindromic, 587 multiallelic, 5 merged. Notable: 100 of the original 222 panel SNPs are themselves low-confidence. - DONE (docs, LIVE) —
snp_panel.qmd→https://lasisilab.github.io/sepia/snp_panel.html: works through every source, the dual-build resolution, the confidence rule + live counts, 222-panel-vs-new. +pigment_snp_map.SOURCE.md. - IN FLIGHT (B3) —
code/wider_pca.slurm(job 54657946): the wider PCA on the extended set — all ~1,153 SNPs and high-confidence-only (~453), joint (159 SGDP + high-cov archaics), to show how much the unreplicated tail moves the structure. - NOTE — Lily Heald pushed derived data CSVs directly (
neo_uvi,simons_metadata,simons_whole) — some of the R-page inputs; reconciled cleanly. Chagyrskaya still extracts 0 records in the archaic step (known.noRB-file bug — to fix).
2026-07-24 — B2a COMPLETE: the pigmentation-panel bug is fixed; corrected PCA recovers real structure; site live
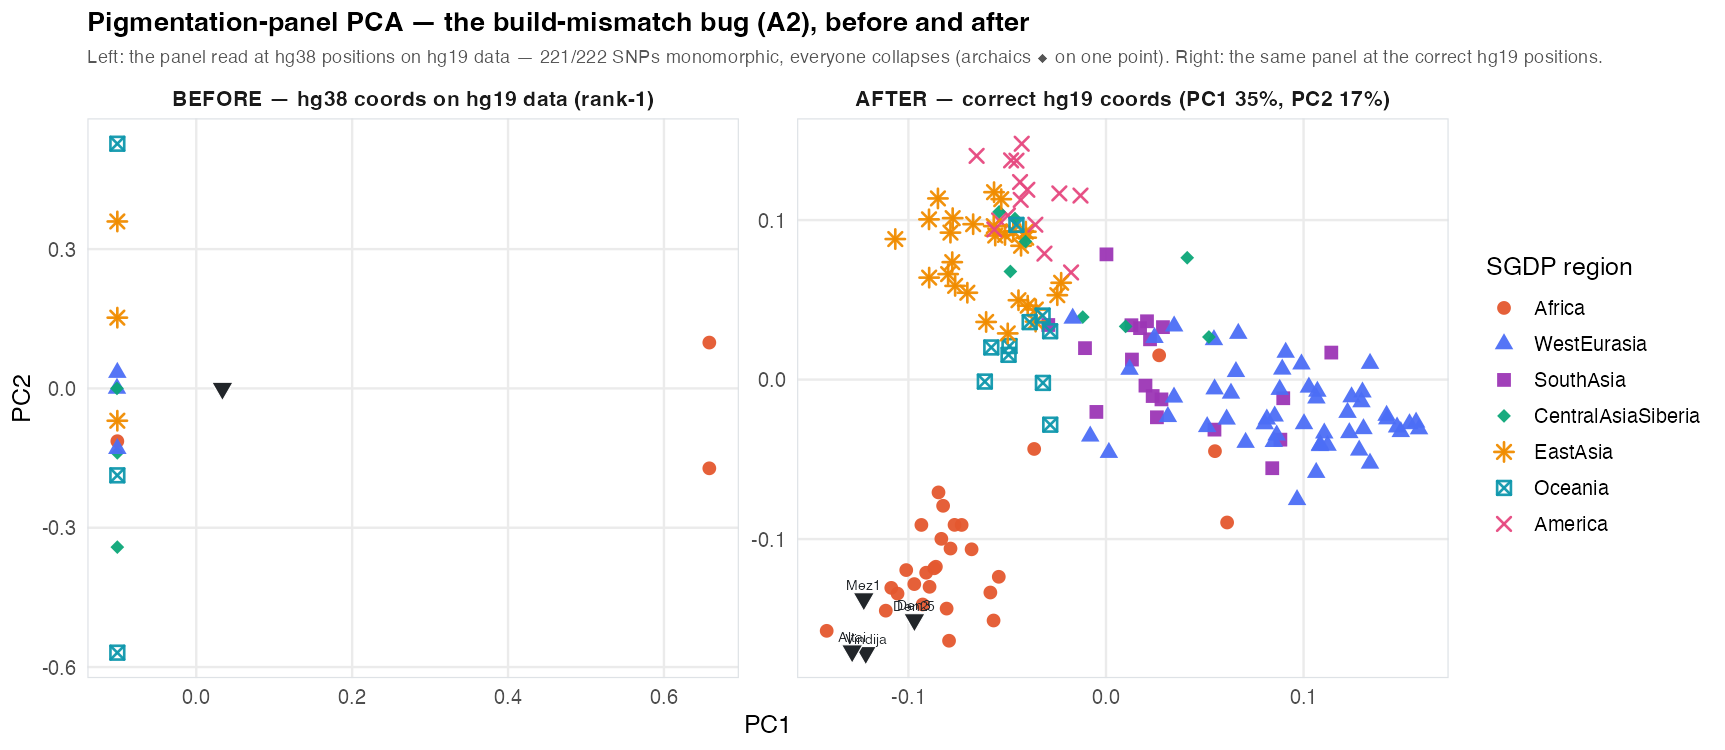
- DONE (B2a result) — pigmentation-panel PCA at correct hg19 coords (job 54641658): 159 SGDP + 5 high-cov archaics (Chagyrskaya pending its VCF re-fetch), 160 informative SNPs. Joint-PCA eigenvalues 31, 15, 8.4, 6.6, 5.7 … (PC1 ≈ 35%) — multi-component, not the rank-1 collapse of the buggy run (
0.063then ~3e-18). Moderns spread by region; the 5 archaics cluster together near the African end of the pigmentation axis. Directly reverses A2. Output committed from the cluster (8a1d5e2) →output/pca_pig/. - DONE (figure) —
plan/figures/pig_pca_before_after.png(make_pig_before_after.R): Lily's degenerate rank-1 (all archaics on one point) vs the corrected real structure. Wired into the plan page as Fig 2 (realized) + the A2 evidence toggle; the "For Lily" A2 note is now past-tense ("it works"). - FIX (B2a job) — the first run streamed 4 GB all-sites per-chr archaic VCFs with
-T(hours); switched the archaic extraction to-Rindexed seek (222 positions = instant). Cancelled54637442, resubmitted54641658. - DONE (site is live + current) — the Quarto deploy was stuck (CI has no R; the thesis analysis pages need a data-bearing local render for
_freeze/). Restrictedproject.renderto CI-buildable pages (index/about/license + the now-frozensgdp_reference_pca), dropped the three R pages from the navbar until_freeze/exists, and deployed. Live: https://lasisilab.github.io/sepia/ (roadmap at/plan/sepia-plan.html). Cluster repo synced; cluster→GitHub push re-verified.
2026-07-24 — B2a submitted; SGDP before/after figure; the plan page now teaches the findings to Lily
- DONE (figure) —
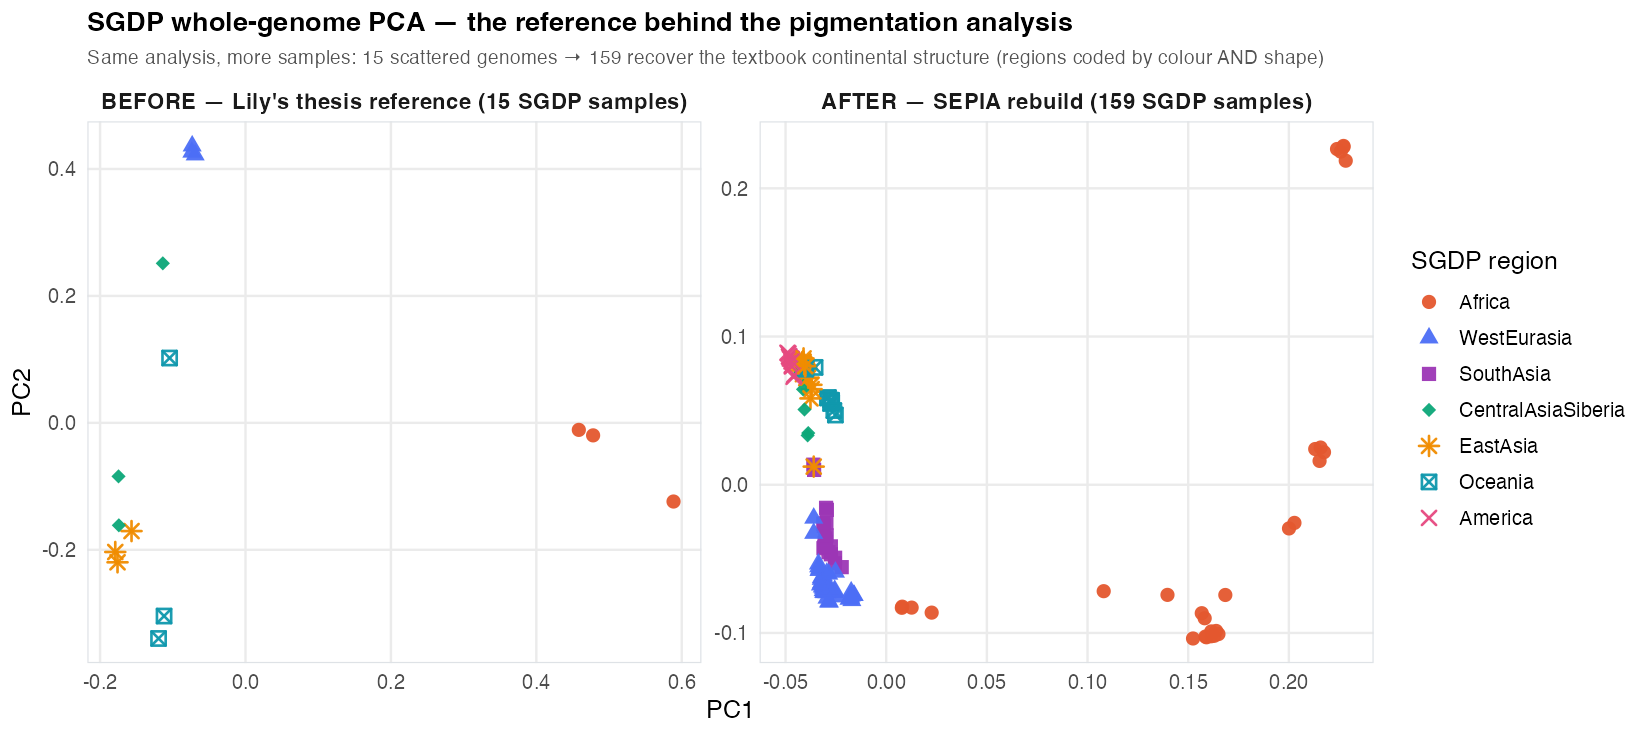
plan/figures/sgdp_pca_before_after.png(+make_sgdp_before_after.R): the SGDP whole-genome PCA — Lily's 15-sample thesis reference vs the SEPIA 159-sample rebuild, coloured by SGDP region (158/159 + 15/15 samples joined via the metadata's LP library IDs). Both PCAs are healthy (the WG panel was never hit by the build bug); the point is the reference — 15 scattered genomes → 159 recover the textbook continental layout (PC1 ≈ African vs non-African). Added as Fig 0 in the plan page's figures section. - DONE (plan page) — rewrote "For Lily" from "please confirm" into "what we've ascertained": A2 / A1 / A3 explained in plain language with the lesson + fix for each, plus the 15→159 reference upgrade — addressed to her, so she can learn. Embedded the demonstrating before-figure + an AFTER placeholder inside the A2 (projection collapse) and A1 (Denisova-3 coverage) evidence toggles (they had reproduce-commands but no figures — the gap Tina flagged).
- IN FLIGHT (B2a) — submitted
code/pig_panel_extract.slurm(job 54637442): extract the 222 panel at correct hg19 coords from the 159 SGDP + 6 high-cov archaic snpAD VCFs → a JOINT pigmentation-panel PCA (moderns + archaics together, so noallele-wtsprojection modifier the 2019 plink2 lacks). Self-validates via the Vindija SLC24A5 tracer @15:48426484. Output →output/pca_pig/; the corrected pigmentation figure replaces the AFTER placeholders when it lands. Projection-based version (Lily's exact method) follows with the plink2 upgrade that also unblocks Sanity 2.
2026-07-24 — Replication strategy confirmed: extract the 222 panel at correct hg19 coords → redo Lily's figures (hg38 is the integration layer, not needed to replicate)
- DECIDED (TL) — the cheapest correct fix for the A2 build-mismatch bug, and step one of the project, is to re-extract the 222 panel SNPs at their correct hg19 coordinates from the hg19 SGDP + archaic data and regenerate Lily's pigmentation figures (PCA, projection, depth). No liftOver, no re-alignment — the genomes are physically hg19, and the panel's hg19 coordinates were always correct (only its hg38 coords were wrong). This directly reverses A2: Lily extracted at hg38 positions on hg19 data → 221/222 SNPs went monomorphic; extracting at the right hg19 positions restores the real variation.
- Already in hand — the "repull the 222 with hg19 coords" is effectively done:
data/panel_hg19_hg38_map.tsvcarries authoritativepos_hg19for all 222 (Ensembl-by-rsID). So B2a needs only: build the hg19 BED frompos_hg19, extract, re-run the PCA/projection/depth. Not yet run — that's the next cluster job (B2a→B3). - CLARIFIED (no backwards work) — hg38 is not required to replicate Lily. It is the reporting/integration layer for the bigger question (joining to the
pigmentation-gene-networkGWAS superset + HIrisPlex-S, which are hg38). The map holds both builds keyed by rsID, so the hg19 extraction and the later hg38 integration share one artifact — nothing built for hg38 is wasted, and the replication path is hg19-native and cheap. - DOC — corrected the SLC24A5 hg38 tracer
48,134,288→48,134,287in thesepia-plan.htmlglossary + Q2 definitions (the tracer entry now notes the panel's stored48,134,288is the +1); made the plan-page glossary collapsible (folded by default). Bug-evidence citations of the panel's stored48134288left intact.
2026-07-24 — Panel rsID↔︎hg19↔︎hg38 map built (B2a); found a +1 off-by-one in the panel's hg38 coords
- DONE (B2a map) —
data/panel_hg19_hg38_map.tsv(+.SOURCE.md): all 222/222 panel SNPs resolved to authoritative GRCh38 + GRCh37 coordinates + per-build ref/alt (Ensembl REST, dbSNP-checked). Columns:rsid, chrom, pos_hg38 (corrected), pos_hg19, ref/alt per build, gene, strand_ambiguous, panel_pos_hg38 (original — traceability), status, notes. 11 palindromic SNPs flagged for Q4; 9 merged rsIDs (old→current); 126 multiallelic; GRCh38/GRCh37 allele strings identical (no cross-build strand flips). This is the hg38↔︎hg19 bridge B2/B2a needs — keyed by rsID, so robust to the coordinate bug below. - FOUND (new — refines A2): the panel's hg38 coordinates are systematically +1 (a 0/1-based off-by-one). Uniformly across all 222 loci,
snps.txt pos − true GRCh38 pos = +1(chrom matches 100%) — introduced whensnps.txtwas built from a 0-basedlocationscolumn. So the true hg38 tracers are SLC24A5 rs1426654 =15:48134287(the panel stored48134288) and HERC2 rs12913832 =15:28120472(panel stored28120473). The rsID map re-pulls authoritative coords, so it caught and corrected this — validating the rsID-bridge approach (don't trust the panel's stored coords). hg19 coords were correct (48426484/28365618), so the genome-wide / SGDP work is unaffected. - FOLLOW-UP (docs) — the tracer definitions (glossary / Q2 / the "single decisive build check") cite the old
48134288as rs1426654's hg38 coord → correct to48134287when we build the Q2 lint. Leave theBUG_EVIDENCE/A2 citations of the panel's48134288as-is (they correctly quote the buggy stored value) — just note it's this off-by-one.
2026-07-24 — Archaic data acquired to the shared resource; cluster→GitHub push fixed (SSH + SSO)
- DONE (archaic acquisition — round 1 + fixes → round 2) —
code/acquire_archaic.slurmround 1 completed: 5 of 6 high-coverage genomes fully downloaded to/nfs/turbo/lsa-tlasisi1/genomes/archaic/vcf/— Altai/Den5, Denisova 3, Denisova 25 (turned out not gated), Mez1, Vindija 33.19 (23–24 chr snpAD VCFs each, ~258 GB) — integrity-verified (Denisova SLC24A5 tracer at hg1915:48426484). Two gaps hit URL/server problems → fixed + re-running (job 54632488): Chagyrskaya 8 (ftp://blocked on the compute node →http://, 302-followed), Vindija-tree FilterBed masks (they live in per-genome subdirs), low-cov BAMs Les Cottés/Denisova 11/Goyet (ENAftp://threw 502/503 →https://).fetchnow skips already-complete files, so the re-run only fills the gaps. Provenance ledger atgenomes/archaic/MANIFEST.tsv(the archaic half of Q1). - DONE (infra — resolves the earlier OPEN) — the cluster checkout can now push to GitHub: switched the remote to SSH (
git@github.com:lasisilab/sepia.git); Tina added an SSH key on Great Lakes and authorized it for thelasisilabSAML SSO — the missing step (the key authenticated astinalasisibut couldn't touch the org repo until SSO-authorized).git push --dry-run→Everything up-to-date. (The original block was the HTTPS remote with no cached creds — the SSH key was never even consulted; both are fixed now.) Results (PCA coords, QC tables, manifests) now sync straight from Great Lakes — no laptop relay. - STATUS — modern reference built + Sanity 1 passed; archaic high-cov VCFs in place; Chagyrskaya + low-cov BAMs finishing. Parallelizable next-work mapped in
plan.md§2.
2026-07-24 — Sanity check 1 PASSED (159-sample modern reference); archaic acquisition launched
- DONE (merge — architecture-sensitive on NFS, took 3 tries) — plain merge of all 34M all-sites × 159 was slow;
bcftools merge -R <1.4M scattered regions>was catastrophic (an index seek per region on the Turbo NFS → ~800 rec/min ≈ 28 h). Fix: stream-thin each sample once with-T(sequential reads, NFS-friendly) across 16 cores, then merge the small results → completed in 11.5 min (job 54603634). 7 truncated SGDP BCFs dropped → a 159-sample reference ingenomes/SGDP/; PCA coords committed tooutput/pca_wg/. - RESULT — Sanity check 1 PASSED. The rebuilt 159-sample SGDP PCA recovers textbook global structure: PC1 separates Africa from the rest; PC2 spreads West-Eurasia/South-Asia ↔︎ East-Asia/Oceania/America; eigenvalue decay is dominant-PC1 (PC2/PC1 = 0.43) vs the flat 15-sample legacy (0.67). The earlier degeneracy was the 15-of-166 partial merge — now fixed; the modern reference is trustworthy. (Figure rendered inline; durable version =
sgdp_reference_pca.qmd.) - DONE (archaic acquisition launched — job 54607824) — per the approved plan,
code/acquire_archaic.slurmpulls archaic data into the shared lab resource/nfs/turbo/lsa-tlasisi1/genomes/archaic/(symlinked asresources/genomes; reusable by other lab studies): high-cov → published snpAD VCFs + FilterBed masks (Altai/Den5, Vindija 33.19, Denisova 3, Mez1, Chagyrskaya 8, Denisova 25-provisional); low-cov → BAMs (Les Cottés, Denisova 11, Goyet) for ANGSD GLs + mapDamage. Resume-safe, integrity-checked,MANIFEST.tsvprovenance (Q1). High-cov VCF URLs validated; mask + BAM URLs resolve at runtime (best-effort) → verify from the log. - OPEN (infra) — the cluster checkout can't
git push(HTTPS clone, no GitHub creds), so results are committed from the laptop for now. Fix: add a read-write deploy key or PAT on the cluster so the "results sync via git" model works end-to-end from Great Lakes. - NEXT — read the acquisition log (confirm VCFs; fix any mask/BAM URL gaps); then Sanity check 2 (project the archaic calls onto the modern PCA); then B2a (panel on hg38 via the rsID map — Step 1, validating Lily).
2026-07-23 — Build strategy settled: report/integrate on hg38, bridge the hg19-native genotypes by an rsID map
- DECIDED (Tina) — the project's reporting/integration build is hg38 (the field standard, and the build of the
pigmentation-gene-networkdatasets + the GWAS Catalog we're integrating). The raw archaic/SGDP genotypes stay physically on hg19 (that's how MPI-EVA published the archaics — BAMs only). We bridge with a verified rsID ↔︎ hg19 ↔︎ hg38 map (both coordinates + per-build ref/alt per SNP): read each genotype from the hg19 data at its hg19 coordinate and express it on hg38. A genotype is build-independent, so this is lossless relabeling, not re-alignment — and it works for every SNP with an rsID (all panel + gene-network loci). The genome-wide sanity PCA stays hg19 (a control; its coordinates never integrate externally). - CLARIFIED (a false alarm resolved) — "moving to hg38" was briefly feared impossible because re-aligning the archaic reads to GRCh38 is blocked (no public FASTQ). That is a different thing from reporting on hg38: re-alignment is only needed to discover novel variants genome-wide, which is not a project goal — the pigmentation analysis is locus-focused, so coordinate relabeling by rsID fully delivers hg38. So there is no dead end.
- DONE (roadmap reconciled — twice) — the early roadmap said "put everything on hg38"; mid-session I over-corrected it to "hg19" (optimizing for the cheap genome-wide control); this settles it as hg38 reporting build + hg19 physical data + rsID bridge. Updated across
plan.mdandsepia-plan.html: A2, B2 (header/What/Why/Do + B2a/B2b), the Phase-1 gate + phase-overview goal, the "single most unblocking step" text, the open-questions item, and the 17-Jun call mapping. B2 is now "build the verified rsID↔︎hg19↔︎hg38 locus map and report on hg38," not "move data." B2b (genome-wide genotypes physically on hg38, via VCF liftover or re-alignment) is optional/deferred — only if a genome-wide hg38 product is ever needed. Factual hg38 mentions (panel from the hg38 GWAS Catalog; the four datasets; tracer coordinates) unchanged. - STATUS — genome-wide branch already hg19-verified (tracer rs1426654 at
15:48426484). Remaining build work: build the rsID dual-coordinate locus map (Q1/Q4) + the Q2 lint, in the pigmentation-panel arm (Phase 4). Step 1 = validate Lily's 222-SNP result correctly, reported on hg38; bigger goal = extend to the gene-network's gene-level data (B1 → B3/B4/B6/B7), same hg38 coordinate system.
2026-07-23 — Why 7 SGDP BCFs dropped from the merge (truncated local copies, not source quality)
- FOUND — 7 of the 166 per-sample SGDP BCFs in Lily's
sgdp/subsets/are truncated local copies: near-full size (~460–528 MB, vs ~510 MB for good ones) but missing the BGZF end-of-file marker and unindexed (.csiabsent), so bcftools cannot read/merge them. The other 159 are complete (valid EOF + index). Affected:LP6005519-DNA_{G02,G03,G04,H04},LP6005592-DNA_{A04,B02,B04}— clustered on two plates. - CAUSE —
get_simons.slurmbuilt each BCF by streaming a presigned S3 URL with no completeness check (wget -q -O - "$url" | bcftools view -Ob, thenbcftools index). When a stream dropped or a URL expired mid-download (those URLs expire 48 h after minting; the job had 40 h wall-time), wget ended early, bcftools wrote an incomplete BCF, andbcftools indexfailed silently (-q). The clustering on consecutive samples is the signature of interrupted download stretches. SGDP source data is fine; the local copies are incomplete — the exact input-integrity gap SEPIA's Q1 (provenance + checksums) exists to catch. - DECIDED — proceed with the 159-sample reference (still spans all 7 SGDP regions; ample for the reference PCA). Re-acquiring the 7 for the full 166 needs fresh SGDP access (expired URLs) — logged as a follow-up; any re-download must verify per-file EOF + index.
code/wg_modern_merge.slurmnow validates/indexes each BCF and drops (with a logged list) the unusable ones instead of letting one truncated file abort the merge.
2026-07-23 — Cleanup, shared lab genomes, and Sanity check 1 (SGDP PCA) submitted
- DONE — deleted the redundant
quarto-migrationbranch (local + remote; fully merged into main) and removed the vestigial workflowrdocs/(457 files — regenerable in Quarto; theintrogression_appsource is kept inanalysis/). Renamed the local working folderpaint-workflowr→sepia(git/remote intact; cosmetic). - DECIDED (salvage vs. scratch) — rebuild the analyses from scratch, following the plan. Salvage only the shell: framing prose (
about,license,introductionbackground), theindexlanding page, the 222-SNP panel +data/skin_pigmentation.tsv, theintrogression_appsource, and the Quarto scaffold. Rationale: the old analysis outputs carry the documented bugs (build mismatch, 15-sample degenerate PCA, mean imputation) and their inputs are laptop-only, so every SEPIA figure is regenerated from the cluster pipeline intooutput/, page by page (sanity_sgdp_pca.qmdis the first). - DONE (shared lab genomes) — created
/nfs/turbo/lsa-tlasisi1/genomes/{SGDP,reference,archaic}as a lab-wide reusable resource, symlinked it into the project (sepia/resources/genomes→ it; gitignored), and made the pipeline honor$SEPIA_GENOMES(default that path). Other studies call the same SGDP reference — no duplication. Options considered: plain absolute path (works as-is on the shared allocation), symlink (repo-relative convenience), env var (portability) — did the latter two on top of the first. - DONE (Sanity check 1) — submitted
code/wg_modern_merge.slurm(job 54590566): completes the 166-sample SGDP merge → reference to the shared genomes dir, PCA coords tooutput/pca_wg/. Addedsanity_sgdp_pca.qmd(in the navbar) — a narrated modern-only PCA check (eigenvalue elbow + PC1/PC2 continental separation, contrasted with the old 15-sample degenerate result); renders once the merge output exists. - OPEN — SGDP region labels (
data/sgdp_metadata.tsv, small public metadata) to colour the PCA; read the merge log + render the sanity page when the job finishes; then Sanity check 2 (project the archaics onto the modern PCA).
2026-07-23 — Executed the reorg: gh rename, Quarto reconciled onto main, cluster cloned
- DONE (rename) — renamed the GitHub repo
lasisilab/paint-workflowr→lasisilab/sepiaviagh(ADMIN confirmed) and repointed the local remote. GitHub 301-redirects old links. Local working folder stayspaint-workflowr(cosmetic — GitHub Desktop labels by folder name; rename at a break, don't while a session is live in it). - FOUND — a pre-existing
quarto-migrationbranch (Tina, 2026-07-22) already migrated the site workflowr→Quarto (clean_quarto.yml, root.qmd,freeze: auto,MIGRATION.md), left unmerged pending "one local render". Rather than build a parallel migration, reconciled it: staged on asepia-quartobranch atop main (which had the full SEPIA rebrand + expanded plan), resolved 3 conflicts (deletedanalysis/_site.yml; took the Quarto render workflow but kept main's richer/plan/copy incl. figures + papers/ + verify/; merged.gitignore), rebranded the Quarto files PAINT→SEPIA preserving the deliberatelilyheald/PAINT+ Lily's-laptop-path references, validated by rendering the prose pages (SEPIA-branded, cosmo), then fast-forwardedmainand deleted the staging branch. Single branch now:main. - DONE (org — repo is the workdir) — cohesive layout:
code/(cluster pipeline;wg_modern_merge.slurmmoved here with repo-relative sepia paths),output/(small synced results — eigenvec/eigenval/sscore/qc/figures), and gitignoredresources/+scratch/(cluster-only big data) plus a BAM/BCF/FA safety net. Results flow into git; big data never syncs. - DONE (cluster) — cleared the old skeleton and cloned
mainas the checkout at/nfs/turbo/lsa-tlasisi1/sepia(251 MB); created the gitignoredresources/{reference,panel,sgdp,archaic_vcf,archaic_bam}+scratch/+output/{pca_wg,pca_panel,qc,figures}inside; verifiedresources/+scratch/ignored and 0 stray tracked changes. Jobs run from this checkout. - DONE (deploy paused) — gated
publish-site.ymltoworkflow_dispatch(was push-on-main): CIquarto renderneeds committed_freeze/for the R-analysis pages, and their data is laptop-only (Lily's) (verified inMIGRATION.md:simons_metadata.csv,ancient_depth_clean.csv,neo_uvi.csv, … absent from repo + cluster). The site goes live once those pages are rendered-with-data or regenerated by SEPIA (the likely path, since we rebuild these analyses anyway). Prose pages already render. - OPEN — delete the now-redundant
quarto-migrationbranch (fully merged into main); eventuallygit rm -r docs/(vestigial workflowr output) after wiringintrogression_appinto Quarto; rename local folder →sepiaat a break; run the modern SGDP merge from the checkout → genome-wide sanity PCA.
2026-07-23 — Renamed the project PAINT → SEPIA; planned the clean cluster reorganization
- DECIDED (Tina) — the project is renamed SEPIA (Systematic Evaluation of Pigmentation In Archaic hominins) to distinguish this forward-looking re-analysis from Lily Heald's original PAINT honors thesis. This repo — a copy Lily made (
paint-workflowr) — becomes the SEPIA anchor and will be published; Lily's original thesis repo on her own GitHub is untouched and safe. - DONE (repo rebrand) — rebranded PAINT → SEPIA across all sources: renamed
PAINT.Rproj→SEPIA.Rprojandplan/paint-plan.html→plan/sepia-plan.html; updatedREADME.md(now a real README + acronym),CITATION.cff(repo/url →lasisilab/sepia, Lily kept as author),analysis/_site.yml(site title + source link → sepia),.github/workflows/publish-site.yml,plan/build_docs.sh, and everyplan/doc; regenerated all 12 generated HTML; SLURM job-namespaint_*→sepia_*. Left Lily'sanalysis/cleaning.Rmdhard-coded local paths (/Users/lilyheald/…/PAINT/) unchanged — her thesis code, flagged as a separate reproducibility fix. Verified zero straypaintoutside generateddocs/(which regenerates from the rebranded sources on nextwflow_build). - TODO (Tina, on GitHub) — rename the repo
lasisilab/paint-workflowr→sepia(Settings → General → Repository name →sepia→ Rename). GitHub auto-redirects old links. Then the local git remote is repointed and pushed. The live Pages site keeps Lily's PAINT thesis content until the workflowr site is rebuilt under SEPIA. - DECIDED (cluster layout) — new project root
/nfs/turbo/lsa-tlasisi1/sepia/(sibling oflheald_thesis/on the 9 TB lab allocation; 8.7 TB free), withrepo/(git clone),resources/(curated read-only inputs: reference, panel, the completed SGDP ref, re-acquired archaic VCFs/BAMs),work/,results/. Stop working inside Lily's thesis folder. - FOUND (cluster inventory) — the whole-genome archaic BAMs are gone (
results/sorted/no longer exists; only tiny panel-regionresults/filtered/*.bam(11 KB–578 KB) + the derivedancient_sgdp_wg.vcf.gzremain), andreference/hg19.fais gone (onlyhs37d5.fa). So genome-wide BAM-level QC (ANGSD heterozygosity, mapDamage) or recalling requires re-acquiring archaic BAMs from ENA/EVA. Modern SGDP is complete (166 samples; fetched via Seven Bridges perwget_commands.txt— presigned URLs long expired). - DECIDED (data strategy) — build
sepia/resources/clean and self-contained (copy small refs; build the completed 166-sample SGDP reference into it; re-acquire archaic published VCFs fresh), reading Lily's folder only once. Do not duplicate the 102 GB of SGDP per-sample BCFs. Leave aREADME_SEPIA.mdin Lily's folder (after resources are built) documenting what was taken/rebuilt + a "safe to delete once SEPIA is validated" list; do not delete her data (Tina's call).
2026-07-23 — Re-scoped to a genome-wide sanity PCA first; found the modern reference is a 15-of-166 partial merge
- DECIDED (Tina) — before any pigmentation-specific analysis, run a genome-wide PCA of ancient + modern samples first — "just for sanity, to see where everyone clusters" — then the pigmentation-loci PCA later. Do basic QC ourselves. Do not optimize a narrow panel-only extraction.
- DONE — Cancelled Stage 0 (job 54578430). It was downloading whole-chromosome all-sites snpAD VCFs (2–4 GB each × 4 genomes × 23 chr ≈ ~275 GB) just to read 222 panel positions — the wrong scope for a genome-wide PCA, and it would overflow the 110 GB working dir. Killed at 12 GB.
- FOUND (validation, kept for the later panel step) — a remote region query works:
bcftools view -r 15:48426484 <EVA-URL>returned Denisova 3 at SLC24A5 with DP=21 in 4.8 s (KB fetched, no bulk download). Confirms the published high-coverage Denisova 3 calls are genuine (the A1 fix) and can be pulled per-site when we get to the panel PCA. - FOUND (the real blocker) — the genome-wide data already exists on the cluster and is build-consistent (hg19):
pca/modern/sgdp.wg(modern, 9.23M SNPs) +ancient_wholegenome/ancient_sgdp_wg.vcf.gz(15 archaics at the SGDP SNP set, 33.5M sites; tracer15:48426484✓, bare-contig GRCh37 ✓). Butpca/modern/sgdp.wgholds only 15 individuals, while 166 per-sample SGDP BCFs sit insgdp/subsets/with amerge_continue.slurmpresent — the modern PCA reference is an incomplete/partial merge. Fifteen individuals cannot define global continental structure — almost certainly why earlier PCAs looked degenerate. Completing the 166-sample merge is the prerequisite for any meaningful ancient-vs-modern PCA. - FOUND (ancient calls are pseudo-haploid) —
ancient_wg.slurmcalls the archaicsbcftools call -m --ploidy 1(haploid) at-q30 -Q30from the sorted BAMs. So individual heterozygosity cannot be computed fromancient_sgdp_wg(no diploid genotypes) → het-vs-depth (Q7) must come from ANGSD on the BAMs. For PCA, the pseudo-haploid ancients should be projected onto the diploid modern PCA (plink2 --pca allele-wts→--score … no-mean-imputation), which also delivers the Q5 no-mean-imputation fix. - FOUND (sample-name hygiene, Q7) —
ancient_sgdp_wg.vcf.gzsample IDs are a mix of full BAM paths and SM-tag names (Vi33.19,L4741,SP4903) — a labeling bug to fix by reheader before merging. - FOUND (degenerate-PCA mechanism, pigmentation branch) —
pca_ancient.slurmuses a different reference (reference/hg19.fa, chr-named) than the WG branch (hs37d5.fa, bare) = the A2 build/naming split, and runsbcftools call -mv(variants-only) on ancients only at panel sites → monomorphic panel SNPs dropped, no modern reference merged in → rank-deficient PCA. Confirms A2 + the projection collapse are isolated to the pigmentation branch and do not contaminate the WG data. - PREPARED (held) — wrote
wg_modern_merge.slurmto complete the modern SGDP merge from all 166 subset BCFs → LD-prune (--indep-pairwise 200 25 0.4) →plink2 --pca 10 allele-wts+--freq(projection basis). Not yet submitted — held pending the project rename + cluster reorganization below (its output paths move tosepia/). - NEXT — reheader + intersect the ancient calls to the pruned modern SNP set, project them onto the modern PCA with
no-mean-imputation(pseudo-haploidize the modern side for a like-for-like comparison), per-sample call-rate/coverage QC (drops the near-empty low-cov archaics), then the "where everyone clusters" figure. Then ANGSD het-vs-depth; then the pigmentation-loci PCA done correctly. - OPEN — SGDP population labels (to colour the PCA): map SGDP library IDs → population/region from SGDP metadata; fetch if not present locally.
2026-07-23 — HTML for every doc + docs hub; verified the "redundant individual" claim
- VERIFIED (Tina's question — same site vs same individual) — checked the only redundancy claim against Hajdinjak 2018: Vindija 87 IS the same individual as Vindija 33.19 (verbatim: "the Vindija 87 specimen originates from the same individual as Vindija 33.19"), so excluding it is correct. Confirmed every other same-site pair is a distinct individual and is kept separate: Mezmaiskaya 1 ≠ Mezmaiskaya 2 (population turnover), and Denisova Cave = four different individuals (Denisova 3 Denisovan, Denisova 5 = the Altai Neanderthal, Denisova 11 hybrid, Denisova 25 second Denisovan). So Mez2's and the Denisovans' decisions are on coverage/reliability grounds, never redundancy. Recorded the evidence in
papers/SAMPLE_INCLUSION.md. - DONE (HTML for everything — Tina prefers HTML over Markdown) — Added a pandoc-based generator (
plan/build_docs.sh+plan/assets/doc-style.html,doc-template.html) that renders every plan Markdown into a styled, theme-aware, self-contained HTML matching the roadmap's design system, with a back-to-roadmap bar and relative.md→.htmllinks rewritten. Generated:changelog.html,rebuild_from_raw.html,b2a_runbook.html,cluster_inventory.html,pipeline_workbook.html,evaluation_plan.html,papers/{REFERENCES,VCF_QC,PIPELINE_QC_BY_PAPER,SAMPLE_INCLUSION}.html,verify/BUG_EVIDENCE.html. Built a docs hub (plan/docs.html) linking everything, added an "All docs" nav entry + hero pointer tosepia-plan.htmlandpipeline.html, repointed their in-site GitHub.mdlinks to the local.html, and updatedpublish-site.ymlto deploy thepapers/andverify/HTML. All 15 HTML pages cross-link with no broken internal links. (Markdown remains the source of truth; re-runbuild_docs.shafter edits.) - NOTE — the changelog has been updated every turn (18+ dated entries); it is now also available as
changelog.html.
2026-07-23 — Decided sample subset (justified), targeted re-acquisition, verify SGDP
- DECIDED (Tina) — targeted re-acquisition; verify SGDP (not rebuild); exclude non-whole-genome (exome) and unreliable genomes; goal = maximize reliably-genotyped pigmentation SNPs of interest, not genome count, with the subset justified explicitly.
- DONE — Wrote
papers/SAMPLE_INCLUSION.md: explicit criteria (whole-genome-only, non-redundant, coverage, reliability-at-transition-SNPs), a quantitative Poisson table of expected usable panel SNPs per genome from published coverage, and a per-genome include/exclude decision. Key basis: the panel is transition-heavy (SLC24A5, HERC2, MC1R are transitions) and aDNA damage falls on transitions, so low-coverage genomes are least reliable exactly at the SNPs of interest; the 5 high-coverage genomes reliably genotype all 222 (incl. transitions) while every low-cov genome yields 0 SNPs at diploid-callable depth. Subset: Tier 1 (core) = Altai/Den5, Vindija 33.19, Denisova 3, Chagyrskaya 8, Denisova 25 + SGDP; Tier 2 (extended, GL uncertainty) = Les Cottés, Denisova 11, Goyet, Mezmaiskaya 1 (VCF); excluded = El Sidrón (exome), Vindija 87 (redundant = Vi 33.19), Mezmaiskaya 2 (1.7×), Spy 94a (1.0× + ~4% contamination), Hohlenstein-Stadel & Scladina (ultra-low ~0.02–0.05×). - CONSEQUENCE (compute) — targeted read re-acquisition needed for only 3 genomes (Les Cottés, Denisova 11, Goyet); high-cov = download VCFs; Mez1 = VCF; SGDP = verify; 6 genomes not downloaded at all. Propagated the decision to
rebuild_from_raw.md(reuse-vs-rerun + net-rerun surface),plan.md§2, and thepipeline.htmlrun log.
2026-07-23 — Per-paper QC & pipeline documented (all 11 sources)
- DONE — Filled
papers/PIPELINE_QC_BY_PAPER.mdfrom a completed paper-extraction workflow (11 sources × extract + adversarial verify; all verdicts SOLID; ~2.2M tokens). Per paper: reference build, read processing (aligner + verbatim params — e.g. BWA-n 0.01 -o 2 -l 16500, leeHom, bam-rmdup), MQ/BQ/length filters, damage handling (UDG vs non-UDG; snpAD vs terminal-masking), genotype calling (tool + ploidy), masks/filters (map35_100, TRF, GC central-95%, min-cov-10, FilterBed), contamination, sex, coverage, and a reuse implication. - FOUND / CORRECTIONS — (1) The published VCF is not the final call set: snpAD VCFs carry only
mq25+map35_100; the min-cov-10 / GC-central-95% (max-depth cap) / tandem-repeat / indel filters ship as a separate companionFilterBedmask that must be applied, then intersected across genomes. (2) The original Altai (Prüfer 2014) and Denisova 3 (Meyer 2012) VCFs are GATK UnifiedGenotyper calls (MQ30, UDG + terminal-BQ masking) — the 2017 snpAD reprocess re-genotyped Vindija/Altai/Denisova (+Mez1) and is the comparable set to use. (3) Mezmaiskaya 1 DOES have a snpAD VCF (…/Vindija/VCF/Mez1/), corrected across the docs. (4) The low-coverage genomes were never diploid-genotyped — Hajdinjak 2018 / Peyrégne 2019 / Slon 2018 used pseudo-haploid random single-read sampling + deamination filter + transversions (heffalump), so our ANGSD-GL plan is a modernization to cross-check against theirs; for HST/Scladina the deamination filter is load-bearing (raw contamination 22.9%/64.8% → 2.0%/5.5%). (5) Denisova 25 data are not yet deposited (preprint) → provisional. (6) El Sidrón endogenous 0.2% (not 2%), ~27 Mb coding. - DONE — Propagated the corrections to
rebuild_from_raw.md(reuse-vs-rerun matrix: Mez1 now has a VCF; added the FilterBed + pseudo-haploid method notes),REFERENCES.md,coverage_current.tsv, and thepipeline.htmlrun log.
2026-07-23 — Reuse-vs-rerun logic (per genome) + per-paper QC extraction underway
- DONE (the "what we rerun" specifics) — Added a per-genome Reuse vs. rerun matrix to
rebuild_from_raw.md: for each genome, what we take as source of truth, whether we re-call, exactly what we rerun, and why. Net surface: the 5 high-coverage genomes are not re-acquired and not re-called (take the publishedsnpADgenotype VCFs, only harmonize/lint/subset); only ~8 low-coverage genomes are re-acquired (targeted) → ANGSD genotype likelihoods; Vindija 87 reuses the Vindija 33.19 VCF (same individual); El Sidrón excluded (exome-only). Always-rerun list: panel→hg19 lift, contig-naming harmonization, allele lint, coverage/damage/het-vs-depth QC, and the whole PCA/projection (PCAngsd, positive control, no-mean-imputation). Summarized inplan.md§2 andpipeline.html§04. - IN PROGRESS — Launched a paper-extraction workflow (one agent per source paper → adversarial verify) to document, for every genome, what the authors report for QC and their pipeline (Methods + Supplementary), quoting parameters verbatim. Created
papers/PIPELINE_QC_BY_PAPER.mdas the target doc (stub now; filled from the verified extractions). This is the evidence base for reusing each published call set responsibly.
2026-07-23 — Full per-genome provenance, paper PDFs, and published-VCF QC docs
- DONE (provenance, all 15 + SGDP) — Two background research agents (verified against MPI-EVA / ENA / the papers) established the source for every genome; only 6 of 15 archaic sources were recorded on the cluster. Compiled into
papers/REFERENCES.md: per-genome canonical name, site, type, coverage, source paper + DOI, exact VCF/BAM/ENA URLs, and data tier. Tiering: Tier A (high-coverage, use published snpAD genotype VCFs — Altai/Denisova 5, Vindija 33.19, Chagyrskaya 8, Denisova 3, Denisova 25); Tier B (low-coverage, BAM-only → ANGSD GLs — Denisova 11, Goyet, Les Cottés, Spy, Mez1, Mez2, HST, Scladina); Tier C (El Sidrón 1253 — exome-capture only, no shotgun genome → excluded, explains "14 analyzed"). Corrections captured: EVA VCFs are unphased snpAD genotype calls, not phased; Denisova 11 is low-coverage (~2.6×) not high; Vindija 87 is the same individual as Vindija 33.19 (so a genotype VCF exists for it); Denisova 25 is from a 2025 preprint (provisional). - DONE (VCF QC docs) —
papers/VCF_QC.mddocuments exactly what QC each published VCF already carries — the 2017 snpAD release (hg19, MQ ≥ 25, Heng Li 35-mer mappabilitymapab100, damage-aware ML genotype, mappable-regions only), Chagyrskaya (.noRB+ separateFilterBed), Denisova 25 (L35 MQ25 B30 map35_100+FilterBed) — plus the cross-genome harmonization we still must add (apply each release's mask, intersect to a common mask, uniform depth band) before merging, since the releases are independent. - DONE (papers) — Pulled the open-access PDFs (Peyrégne 2025 Den25 preprint, Prüfer 2017 Vindija author copy, Peyrégne 2019 HST/Scladina) into
plan/papers/pdf/which is git-ignored — the repo is public and most of these are paywalled, so committing them would redistribute copyrighted material; paywalled ones (Prüfer 2014, Meyer 2012, Slon 2018, Mafessoni 2020, Hajdinjak 2018, Castellano 2014, Mallick 2016) are linked by DOI for UMich-library download into the same folder. - DONE (coverage + provenance wired in) — Updated
coverage_current.tsvwith confirmed published genome-wide coverage per sample (flagging realized-vs-published gaps for Q6, e.g. Altai ~52× published vs 16× realized). Added a full-provenance callout + El Sidrón exome-only fix + run-log entries topipeline.html; noted the genome-level Q1 progress inplan.md; recorded the Tier-A "use published VCFs" data-form choice inrebuild_from_raw.md(with the snpAD-not-phased and Denisova-11-is-low-cov corrections).
2026-07-23 — Genotype likelihoods (ANGSD), exact coverage, contig explainer, BAM-only confirmed
- DECIDED (method) — Adopted genotype likelihoods (ANGSD) + PCAngsd as the primary engine for the low-coverage archaics, replacing hard genotype calling (Tina's point that hard-calling with VCF tools is inappropriate for archaic samples). Exact panel coverage shows why: 10 of the 14 samples are under ~3.2× and several under 1×. Updated
rebuild_from_raw.mdStage 4 (GLs via ANGSD; hard calls reserved for the 4–5 high-coverage genomes + per-SNP reporting) and Stage 6 (PCAngsd on the GLs). Added a max-depth cap to the calling stage — the current data already shows pileup artifacts (Vindija 87 mean 3.2× but max 147×; Scladina 1.9× / max 91×). Transversion-only is applied only to the ancestry PCA (not the transition-heavy pigmentation panel). Noted the GL approach inplan.mdB3 (posterior dosages for the score) and B4 (PCAngsd for the PCA), and added glossary entries: contig, genotype likelihood vs hard call, ANGSD/PCAngsd. - DONE (coverage documented exactly) — Committed
coverage_current.tsv: exact per-sample mean/max panel depth + covered/222, computed from the committed*_depth.txt, with explicit caveats (measured at the mis-located hg38 coordinates; Denisova 3's 0.5× is the A1 artifact, true ~30×; max≫mean = pileup artifact; published/expected coverage to be recorded in the Q1 manifest). Rendered as a table inpipeline.html§02. - FOUND (thesis §2.3) — Confirmed the archaic data was taken as BAM files "previously mapped to GRCh37/hg19" — no FASTQ, no alignment/adapter-trimming/collapsing done in-house. Modern SGDP came as VCFs (hg19). This makes rebuild-on-hg19 the practical choice (re-mapping to hg38 would need FASTQ + full re-alignment, and MPI-EVA genomes are published only as processed BAMs). Recorded in
rebuild_from_raw.md(build decision),pipeline.html(§02 callout + §04), and here. - FOUND (fair to Lily) — Thesis §2.6 states "no imputation was performed and projections only reflect observed genotypes" — the correct intent; but the
plink2 --scorecode lackedno-mean-imputation, so plink silently mean-imputed anyway, causing the collapse. The method text was right; the implementation didn't match it. Noted inpipeline.html§04. - DONE (docs) — Wrote out "contig" in full (definition +
@SQ SN:header + bare-vs-chrnaming → the A1 mechanism) in bothplan.mdglossary andpipeline.html§03; updated the run log and the Lily-vs-rebuild comparison table.
2026-07-23 — Cluster probe, rebuild-from-raw decision, and the Data & Pipeline living doc
- FOUND (cluster state) — Probed Great Lakes over the authenticated socket (text-only). The full sorted archaic BAMs are gone —
work/bamlist.txtlists paths underwork/bam_chr/but that directory does not exist; only the wrong-regionresults/filtered/filtered_*.bam(5 K–565 K) and the already-called VCFs remain. The modern referencepca/modern/sgdp.wgis intact and hg19 (15 samples × 9.2 M SNPs) and contains the pigmentation SNPs by rsID (confirmed SLC24A5 rs1426654 → 15:48426484, HERC2 rs12913832 → 15:28365618). The archaic whole-genome VCFancient_sgdp_wg.vcf.gz(1.6 G) is present. Of the ~225 unique panel rsIDs, 129 overlap the modern reference; 92 are transitions, 37 transversions — so a blanket transversion-only filter would drop the crown-jewel pigmentation SNPs (SLC24A5, HERC2, MC1R red-hair are all transitions). Disk is ample (Turbo 8.7 T free, scratch 300 T). - DECIDED — Because the derived data has confirmed QC failures and the raw BAMs are no longer on the cluster, we rebuild from the raw public BAMs rather than trust/patch the existing products. Wrote
rebuild_from_raw.md: a clean-slate, QC-gated pipeline (Stages 0–8) that executes Phases 0–4 ofplan.mdfrom raw — provenance+checksums (Q1), re-acquire reads (targeted vs full, with compute estimates), raw QC incl. mapDamage/sex/contamination/coverage (Q6/Q7/Q8), panel→hg19 by rsID + tracer/allele lint (Q2/Q4), proper re-calling (diploid autosomes fixing A3, keep-all, max-depth cap, mapDamage-rescale, transitions-kept-for-pigmentation / transversion-only-for-ancestry), PCA with positive control +no-mean-imputation(Q3/Q5), then score/functional + reproducibility (Q10). Per-stage compute table included; targeted re-acquisition makes it roughly a half-day, mostly-download job on one standard node. This supersedes the "patch the panel" quick route inb2a_runbook.md(kept as an optional preview). - DONE — Built
pipeline.html: a shareable living Data & Pipeline record — BAM-vs-VCF explainer (with the crime-scene-photos-vs-detective's-findings analogy), the raw public-data provenance table (MPI-EVA / EBI-ENA, per sample), a colour-coded data-flow diagram marking the BAM→VCF boundary, a side-by-side of what Lily's pipeline did vs the rebuild, an "are the samples the same?" table, and a run log that updates as we execute (seeded with the audit → probe → rebuild-decision entries). Linked from the roadmap HTML nav + hero and fromplan.md§2. - NOTE (scientific) — Incorporated Tina's requests: mapDamage + max-depth cap are in the rebuild's calling stage; the transversion-only request is applied only to the ancestry PCA (not the pigmentation panel, which is transition-heavy) — flagged with the 92/37 Ti/Tv count so the trade-off is explicit.
2026-07-23 — B2a runbook (detailed, runnable) + compute/access needs
- DONE — Wrote
b2a_runbook.md: a step-by-step, ready-to-run plan for the fast build fix (panel → hg19). Covers (1) what's needed from the team — cluster access via an authenticated Great Lakes SSH session/ControlMaster socket (Claude never handles the password/Duo; alternatively the user submits the script and pastes back outputs), plus a small parameter table to confirm (accounttlasisi0, partition, paths, SGDP reference = the 15-sample merged VCF that matches the committed PCA, modules); (2) compute — one standard node, ~8 cores, ~32 GB, ~2 h, ~5 GB scratch, no GPU/large-mem, because every step is restricted to the 222 panel positions (no whole-genome op); (3) the steps with exact commands — liftOver the panel hg38→hg19 (+chr→bare, tracer-SNP Q2 gate),samtools reheaderDenisova 3 (A1), re-extract panel depth (raw + q30), subset the SGDP moderns and build the reference PCA withallele-wts, call archaic genotypes and project withno-mean-imputation(the Q5 fix), QC gates (Q2/Q4/Q5/Q6), and regenerate the after-figures; (4) acceptance criteria and what B2a deliberately does not cover (B2b, Q3/Q7/Q8). Grounded in the committed panel format (222 hg38chr:pos, rsIDs recoverable fromskin_pigmentation.tsv) and the 15-sample SGDP PCA. Linked fromplan.mdB2 and the shareable HTML.
2026-07-23 — Build-fix execution plan + before/after consequence figures
- DONE (figures) — Added a reusable R script
figures/make_consequence_figures.Rthat renders the bugs' fingerprints straight from the committed (pre-fix) outputs, and committed the three before PNGs:before_coverage.png(Denisova 3 recovers at 0.5×/69-of-222, sitting among low-coverage samples — the A1 fingerprint),before_projection.png(all 15 archaics collapse to one point on the pigmentation panel vs spread on the whole-genome panel; the two Denisovans split apart — A2 + projection collapse + A1), andbefore_scree.png(pigmentation PCA is rank-1: one nonzero eigenvalue vs the healthy declining whole-genome spectrum — A2). Re-running the script withafteron the corrected outputs produces the matchingafter_*.pngfor a like-for-like check. Added a "Before / after — the errors in pictures" section tosepia-plan.html(embeds the three before figures with after-placeholders), a nav link, and updated.github/workflows/publish-site.ymlto copyplan/figures/into the published site so the figures resolve at/plan/. - DONE (build-fix plan) — Answered the data question directly in
plan.mdB2: no new data is needed from anyone. The hg19 BAMs are already on the cluster, the 222-SNP panel is committed, and the chain file / GRCh38 reference / public raw reads are all fetchable — the only dependency is re-establishing Great Lakes cluster access (Kerberos + Duo). Wrote a staged B2 execution plan: B2a (panel → hg19; fast and lossless — liftOver or re-pull hg19 coords by rsID keeping both builds, verify with Q2, re-run depth + PCA + projection withno-mean-imputation, fix A1 in the same pass, regenerate the after-figures) done first for the integrity check and before/after; then B2b (migrate the data to hg38) for the integration phase (prerequisite for B1/B3/B4). Recommended order recorded as the default; the B2a-vs-B2b choice flagged as the one open decision. - DONE (consistency) — Mirrored the consequence claims and the B2 execution/"no new data" answer into
sepia-plan.html, and added an evidence-log link in the figures section. Verified plan ↔︎ HTML ↔︎ changelog agree: 7 per-bug Consequence lines present in bothplan.mdand the HTML; figures referenced in both; all tables intact; HTML tags balanced (13 sections, 3 figures).
2026-07-23 — Downstream-consequence evidence for every bug + "QC done vs. to add" note
- DONE — Added a "QC already in place vs. what these phases add" section to
plan.md§4 (and mirrored it insepia-plan.html): credits Lily's existing QC (the coverage/depth + missingness arm — per-sample panel depth, theglmermissingness model, and confidence simulations with a read-end/damage term — plussamtools quickcheck, MAPQ/BaseQ≥30 in WG calling, LD-pruning, biallelic filtering, reference-frequency projection, and the honest "not yet well-supported" framing), and states exactly whatQ1–Q10add and why the three serious bugs slipped through. Notes that quality filtering was inconsistent (present in WG calling, absent in the depth step and pigmentation calling). - DONE (evidence) — For every bug, traced the error forward to its downstream consequence and adversarially verified each claim against the committed outputs, the R pages, and the thesis (multi-agent workflow: thesis index → 9 per-bug gatherers → 9 skeptical verifiers; ~1.5M tokens; all checks local, no cluster/SSH). Wrote the results into
verify/BUG_EVIDENCE.mdas tagged [DEMONSTRATED] / [NONE] / [LATENT] blocks, and added a one-line Consequence pointer to each bug inplan.md+sepia-plan.html. Key confirmed consequences:- Build mismatch (A2): pigmentation PCA is rank-1 (
pigmentation.pca.eigenvalPC1=0.063, PC2–10≈3e-18); 221/222 SNPs have zero loadings, only non-canonical rs76285708 loads; modern PC1 has just 3 discrete values → the thesis's "PC1 differentiates Bantu/Yoruba" and "archaics near Africans / small number of loci" (Fig 8, §3.5, Discussion p.32) are one-SNP artifacts. - Projection collapse:
data/ancient.projected.pig.sscorehas byte-identical PC coords for all 15 archaics (PC1=0.0335547) despite differing dosages; the WG projection does not collapse → Fig 8 stacks every archaic on one point; the "cluster with Africans" headline rests on that single point (which is 4.6× closer to the non-African cluster). - Denisova 3 (A1): committed depth = 0.5×, 69/222 (vs Vindija 30.7×, 222/222); Fig 5 shows a 30× genome in the sparse band, contradicting the thesis's own Table 3; in the WG projection it sits at the empty-sample point (PC1 +0.011) not with Denisova 25 (−0.058).
- Honest [NONE] findings (conclusion survives): the whole-genome PCA (Fig 7) is unaffected by the build bug; the aggregate missingness direction survives; the WG-PCA conclusion survives the
--ploidy 1bug; A4 (-mv) and A5 (dead scripts) left no downstream trace (ALLELE_CT=444 proves the-coutput was scored; no artifact traces to the dead scripts).
- Build mismatch (A2): pigmentation PCA is rank-1 (
- FIX (self-correction) — The audit overturned two earlier notes, now corrected in
pipeline_workbook.md: (1) theglmerfit is not singular —Coverageis a 2-level grouping whose variance (13.0, from 2 groups) is unidentifiable and dwarfsSample(0.99); and the page's prose coefficients (age β=1.34, chr β=−0.02) come from a different model (numericChromosome, indepth_spinoff) than thefactor(Chromosome)model it fits (which makes chr5 non-significant at p=0.094, though the thesis lists it as significant). (2) The Monte Carlo is not unseeded in effect — workflowr injectsset.seed(20251106)from_workflowr.yml, so the committed Fig 6 reproduces as built. - NOTE (A6, reader-facing): confirmed the published site says "395 SNPs" (
introduction.Rmd:284; should be 222), the "View genetic PCAs" link 404s on rebuild,LICENSEis empty, and the committed site cannot be rebuilt from a clean clone (.gitignoredrops*.csv; derived CSVs only written to Lily's laptop paths).
2026-07-23 — Unified master plan: one phased, checkbox-tracked plan.md
- DECIDED / DONE — Merged the two planning docs into a single source of truth.
plan.md§4 was restructured from category-grouped (A bugs / B analysis / C infra / D writing) into seven phases (0–6), ordered as execution order, each a gate that co-locates a fix/build with the QC check that proves it. The 10 reviewer-driven QC checks fromevaluation_plan.mdare now first-class tracked itemsQ1–Q10, fleshed to the same depth as the A/B items (with Verifies/relates · Deliverable · Acceptance · Subtasks · Artifact). Nothing is tracked outsideplan.mdanymore. - DONE — Added a status vocabulary applied to every item (
TODO·IN PROGRESS·BLOCKED(<dep>)·DONE, plus the bug verdictsCONFIRMED/DOWNGRADED), a phase-overview table at the top of §4, and glossary entries for the QC-specific terms (checksum/manifest, tracer SNP, positive control, palindromic SNP, contamination, pipeline DAG). Folded the old §5 "Do B2 first" into Phase 1's ordering; renumbered Datasets→§5 and Name→§6. - DONE (IDs preserved) — All original IDs kept verbatim so
pipeline_workbook.md,verify/BUG_EVIDENCE.md, and this changelog still resolve: A1–A6, B1–B7, C1–C4, D1–D3. 30 tracked items total (A6+B7+C4+D3+Q10), each with a checkbox + status. Phase→item map: P0 Q1 (+Q10a); P1 A2, B2, A1, A3, Q2, Q4, A4, A5; P2 Q3, Q5, Q6; P3 Q7, Q8; P4 B1, B3, B4, B5, B6, B7, Q9; P5 C2, C3, C4, Q10, A6, C1(done); P6 D1, D2, D3. - DONE — Retired
evaluation_plan.mdto a one-paragraph stub (a was→now table pointing each item to itsQ-ID inplan.md) so existing links/changelog references don't break. - DONE — Regenerated
sepia-plan.htmlto mirror the phased plan (reused the existing teal/serif design system; QC items get a distinct left-border card with the acceptance/subtasks structure). Verified: 30 item cards (each ID once), all HTML tags balanced (section/table/details/pre/ul/div), and no literal|leaking into a rendered table (the only pipes left are inside<pre>shell-command evidence — safe).
2026-07-23 — Workbook table fix + reviewer-driven evaluation/QC plan
- FIX —
pipeline_workbook.mdknown-issues table row 7 rendered broken on GitHub: the cell contained literal|inside inline code ((1|Coverage),(1|Sample)), which the Markdown table parser read as extra column separators. Rephrased the cell to drop the pipes. (Verified it was the only such offender; code fences balanced; mermaid diagram fine.) - DONE — Added
evaluation_plan.md: a reviewer-driven, unit-test-style QC/evaluation plan. Works backwards from a skeptical reviewer ("what wouldn't I believe; what are the classic failure modes") into 10 concrete, runnable tests on defined units, ordered by importance. Two principles: provenance-before-analysis, and reproduce-known-truth-first (positive controls). Covers provenance manifest + checksums (genomes, SNP panel, gene coords), build/contig-naming lint (tracer SNPs), the SGDP-PCA positive control, allele/annotation harmonization, PCA/projection non-degeneracy, coverage expectations, sample identity/sex/contamination, aDNA damage, cross-validation vs published results, and reproducibility infra (versions/seeds/DAG/CI). Each item pairs a test with a communication artifact (build-harmonization matrix, SNP funnel, per-sample QC dashboard, auto-generated pipeline DAG). Awaiting Tina's evaluation before implementing.
2026-07-23 — Pipeline audit workbook
- DONE — Wrote
pipeline_workbook.md: a step-by-step, audit-oriented record of the whole bioinformatics pipeline (acquire → depth/filter → archaic calling → SGDP subset/merge → PCA → projection → R analysis). Per step: exact command + tool + module/version, inputs/outputs (path · format · upstream source), key parameters, and a "⚠ Verify" reviewer worklist. Includes a mermaid data-flow diagram, a "which scripts are canonical" table (the pipeline has several competing/dead scripts), a known-issues table, an audit checklist, and a reproduce-from-scratch order. Built by fanning out per-stage extraction over the verbatim script text (repo-only doc; lists cluster paths). - FOUND (new, fixable) — the ancient→modern PCA projection collapse has a second root cause beyond the build mismatch:
plink2 --scoremean-imputes missing genotypes and, with--variance-standardize+ high ancient missingness, every sample collapses to the reference centroid (the committed.sscorehas byte-identical coords for all 15). Fix = addno-mean-imputationto the--scoremodifiers inpca_proj.py. Also confirmedpca_proj.pyis canonical (vspig_pca_proj.py, which additionally omits--variance-standardize).
2026-07-22 — Pages live; Node-24 fix; cluster inventory; methods clarifications
- DONE — Pushed to
mainand the site went live athttps://lasisilab.github.io/sepia/(plan at/plan/). First deploy failed because the Actions token can't create the Pages site in an org repo ("Resource not accessible by integration"); enabled Pages once viagh api -X POST repos/lasisilab/sepia/pages -f build_type=workflow, re-ran → green. Future pushes auto-republish. - DONE — Fixed the Node 20 deprecation in
publish-site.ymlby bumping to verified Node-24 action majors (checked eachaction.ymlruns.using, per prior breakage):checkout@v5,configure-pages@v6,upload-pages-artifact@v5,deploy-pages@v5. - DONE — Removed the stray
docs/.nojekyll 2junk file (was tracked). - DONE — Wrote
cluster_inventory.md: the 110 GB Great Lakes layout by size, the ~19-job pipeline by stage, the 15 archaic BAMs, key derived products, and access/refresh instructions. Repo-only (not published to Pages, since it lists internal cluster paths). - CLARIFIED (methods) — Added to
plan.md§4B and the HTML: (a) a transcript→item map of the exact analyses agreed on the 17 Jun call (toggle in the HTML); (b) how the two dataset types are used — the directional polygenic score is SNP-only (GWAS/HIrisPlex, where each SNP has a signed effect allele), while gene-level sources (Raghunath network, Baxter, Bajpai, D'Arcy) can't enter the +1/−1 score — they feed the gene-level PCA (B4 ii), coverage (B1), and functional annotation (B7) as gene-region sets. A per-gene "direction" would need per-variant damage prediction (optional, descriptive).
2026-07-22 — Self-containment rewrite (no assumed knowledge) + cold-reader audit
- DONE — Rewrote the plan so every item stands alone: added a Glossary (hg19/hg38, SNP, panel, "the data", GWAS/GWAS Catalog, allele, kb, aligned/BAM, genotype calling, SLURM, liftOver, MC1R, HIrisPlex-S, exome, synonymous/non-synonymous, tissue-specific expression, the six skin genes, ploidy…) and gave every roadmap item a What / Why / Do structure. Applied to both
plan.mdandsepia-plan.html. - DECIDED — Disambiguated "the data": it means the sequencing reads for every individual (archaic BAMs and SGDP genomes), all aligned to the hg19 reference — as opposed to "the panel" (the 222-SNP list, on hg38). This phrasing is now used everywhere instead of a bare "the data".
- DONE (verification) — Ran a cold-reader audit (5 agents, each given one section + the glossary only). Scores 2–4/5; fixed everything flagged: named the actual tools in the Do steps (liftOver/CrossMap for build conversion, samtools reheader for A1, VEP/SnpEff/ANNOVAR for B7), corrected the depth-offset magnitude (was "~kb", is up to ~292 kb and varies per SNP), spelled out the diploid polygenic-score rule (allele dosage 0/1/2) and score direction, defined "high-coverage" (the 4 flagship genomes) in B4, clarified that B7's syn:non-syn ratio is over coding variants (not the mostly-non-coding panel), and stated the B2 dependency where analyses need matched-build genotypes.
- FIX — Corrected the manuscript title to "The genetic landscape of pigmentation in archaic hominins".
- DONE — Added public-repo source links (each dataset → its file in
tinalasisi/pigmentation-gene-network) and gave HIrisPlex-S its own labelled row.
2026-07-22 — Evidence pass: reproduced (and corrected) the flagged bugs
Every flagged bug was re-checked with explicit commands + captured output → verify/BUG_EVIDENCE.md (runnable verify/verify_bugs.sh). Results:
- FOUND (root cause, confirmed) — Genome-build mismatch. The committed 222-SNP panel is on GRCh38/hg38 (
data/snps.txthas SLC24A5/rs1426654 at15:48134288, MC1R/HERC2/SLC45A2 likewise) while the reference (hs37d5.faheader = GRCh37) and all data are hg19. Evidence of impact:pigmentation_snps_freq.afreqshows 221/222 sites monomorphic (ALT=".", OBS_CT=30) in SGDP;pigmentation.pca.eigenval= one nonzero eigenvalue (PC1 0.0628; PC2–10 ≈ 3e-18) vs full-rank whole-genome PCA on the same samples;ancient.projected.pig.sscoreidentical across all samples. Depth arm also affected:vindija33_depth.txtreports depth at the hg38 coordinate15:48134288(~292 kb off the true hg19 SLC24A5 SNP). - CONFIRMED — A1 (Denisova 3 chr-prefixed BAM vs bare reference/panels), A3 (
--ploidy 1on autosomes; output GTs single-allele), A5 (ancient_mergeglob matches nothing;pca_ancientneeds missinghg19.fa, outputpca_snpsunused). - CORRECTED / DOWNGRADED — A4. Earlier flagged as "
-mvdrops non-variant sites → ascertainment bias." The committedancient_pigmentation.vcf.gzhas all 222 sites, so nothing was dropped; the-ckeep-all script is the one used. Reclassified as cleanup (delete the unused-mvscript). My earlier framing was wrong for the committed output. - DECIDED — A2 reframed as the build mismatch (root cause) and B2 (hg38 normalization) promoted to the critical path: the pigmentation PCA and pigmentation-SNP depth/missingness results are provisional until build is harmonized. Updated
plan.md§3.A/§4 andsepia-plan.htmlaccordingly. - NOTE — cluster inspection kept strictly text-only (grep/ls/
samtools view -H/bcftools view -H) to avoid a repeat of the binary-to-terminal issue.
2026-07-22 — Cluster inventory, bug hunt, dataset decision, plan docs created
- DONE — Established read access to the Great Lakes cluster over an SSH ControlMaster socket (Tina's authenticated session; UMich requires Kerberos password + Duo, so key-based / the "Add SSH connection" dialog does not work — the terminal socket does). Inventoried
/nfs/turbo/lsa-tlasisi1/lheald_thesis/aDNA_data(110 GB). - DONE — Reconstructed the full pipeline: 19 SLURM jobs (acquire archaic BAMs → depth/filter → ancient calling → SGDP download/subset → merge + PCA → project). Only 4 of these scripts were in the repo; the rest live on the cluster.
- FOUND / confirmed — Denisova 3 chromosome-naming bug (A1). Denisova 3's BAM alone uses
chr-prefixed contigs (SN:chr1,SN:chrM); all other archaic BAMs and thehs37d5.fareference use bare names (SN:1). Evidence:samtools view -Hon the filtered BAMs;Denisova3_depth.txtuseschr1-style labels whilevindija33_depth.txtuses1; the panel exists in bothsnps.bed(bare) andsnps.chr.bed(chr) forms. Consequence: Denisova 3 (a ~30× genome) is under-recovered and appears sparse in thesis Fig 5. High confidence. - FOUND / preliminary — Adversarial bug hunt (multi-agent workflow) run over repo code + the 19 SLURM scripts. Stopped early by Tina because agents streaming raw binary genomics output (
.bcf/.bam) scrambled the terminal display (read-only; nothing damaged). Cause: the finders were given SSH access to a binary-heavy filesystem without a no-binary-dump constraint. Findings below are preliminary — to be re-verified in a clean, local-only pass (no SSH, no binary viewing):- A2 — Pigmentation-SNP PCA panel comes out ~monomorphic (PC1 ≈ 1 SNP; PC2–10 eigenvalues ~3e-18; SLC24A5/SLC45A2 with zero minor alleles). Whole-genome PCA on the same 15 samples is full-rank → it's the panel extraction, not sample count. Suspected coordinate/build mismatch in the SGDP pigmentation extraction (ties to the hg38 decision).
- A3 —
ancient_wg.slurmusesbcftools call --ploidy 1(haploid) across autosomes. - A4 —
pigmentation_ancient_call.slurmusesbcftools call -mv(variants-only), dropping non-variant sites; a second script (pig_call_miss.slurm,-c) keeps all sites. Two competing versions. - A5 —
ancient_merge.slurmglob*.wg.vcf.gzmatches no file;pca_ancient.slurmis dead code referencing a missinghg19.fa.
- DECIDED — Dataset source =
pigmentation-gene-network, notmelanogenesis-constraints. Verified that pigmentation-gene-network already contains all four datasets on hg38 (data/external/gwas_catalog/pigmentation_gwas_catalog.csvwithpos_hg38;bajpai2023_crispr_hits.csv; Raghunath/D'Arcy network tables;baxter2018_650_pigmentation_genes.csv) plus HIrisPlex-S markers (hirisplexs2018_markers.csv, full MC1R red-hair set + blue-eye HERC2/OCA2). Its gene-level GWAS file was frozen from melanogenesis-constraints, so that repo is not needed. - FOUND — HIrisPlex-S model coefficients are the one gap in pigmentation-gene-network (markers present; per-SNP β / intercepts are not — they live in Walsh 2011/2013/2017 + the Erasmus MC tool). Not needed for the directionality PGS; only for quantitative probabilities.
- DECIDED — Confirmed reconciliations against the thesis: the 222-SNP panel is correct (the "395" appears only in the website's
introduction.Rmdprose); advisor/mentor/acknowledgements are in the thesis (the website omitted them); El Sidrón (Sid1253) genuinely has no data → 14 analyzed, not 15. - DONE — Created
plan/docs:plan.md,changelog.md,sepia-plan.html. - DONE — Documented dataset provenance in
plan.md§6 (Raghunath 2015 melanogenesis backbone = curated in-lab as prior SEPIA work; GWAS Catalog / Bajpai / Baxter / D'Arcy / HIrisPlex origins), pointing topigmentation-gene-network/DATA_SOURCES.mdas authoritative. - DONE (uncommitted) — Added
.github/workflows/publish-site.yml: a workflowr-adapted version of the Quartopublish-site.ymldeploy frompigmentation-gene-network. It does NOT re-run R; it assembles the committeddocs/+plan/*.htmlinto a Pages artifact and deploys via Pages-from-Actions (self-enabling). The plan is served at/plan/(direct link, not in the workflowr navbar);plan.md/changelog.mdare kept off the public site. Addedplan/index.html(redirect →sepia-plan.html) andnoindexon the plan HTML. - DECIDED / OPEN — Repo
lasisilab/sepiais public and has no Pages yet (Lily's live thesis site is the separatelasisilab/sepia). Enabling this workflow makes the plan publicly reachable-by-URL (unlisted + noindex, not truly private). Not committed/pushed — awaiting Tina's go-ahead on public exposure vs. a private option.sepiais workflowr, not Quarto; a full Quarto migration would be a separate, larger task if ever wanted.
2026-06-17 — Planning meeting (Tina, Lily, Yemko; from Otter.ai transcript)
Decisions and directions set for the next phase (recorded verbatim-in-spirit; see plan.md §3 for the actionable form):
- DECIDED — Expand the coverage analysis from GWAS-Catalog-only (222 SNPs) to four pigmentation datasets (GWAS Catalog + a CRISPR study + a melanogenesis network + a cross-species/"animal-wide" set), analyzed in a layered way.
- DECIDED — Normalize everything to hg38. (Yemko's data already on hg38; the plan is to standardize the whole project there.)
- DECIDED — Answer "what color were they?" in two steps: (1) GWAS betas → directionality-only polygenic score (+1/−1), optionally skin-only / ≥2-hit; (2) MC1R red-hair-variant check (expected null, reconfirm).
- DECIDED — Redo PCA in three variants (pigmentation SNPs / whole pigmentation-related genes / genome-wide), with two designs (everybody-together vs. moderns-with-ancients-projected).
- DECIDED — Move the repo into the Lasisi Lab GitHub org; set up a PODFRIDGE-style cluster-compatible workflow (Lily develops locally, Tina runs cluster steps).
- DECIDED — Prioritize the TIG review manuscript (no new analysis); keep it differentiated from the primary SEPIA paper. Draft SEPIA title: "The genetic landscape of pigmentation in archaic hominins."
- OPEN — Whether any datasets are gene-level vs. SNP-level (network is genes) — affects weighting; to be checked (now largely resolved by the pigmentation-gene-network structure).
- ACTIONS assigned — Lily: lit review (Undermind → Claude paper screen), move repo, "where everything lives" doc, subset to skin-specific genes. Tina: update code for 4 datasets, curate gene lists, organize cluster runs, target-journal scoping. Yemko: archaic-data API queries (e.g. EGA), skin-specific expression.
~2025-11 → 2026-05 — Thesis development (for reference)
- Honors thesis (workflowr project) developed Nov 2025 – May 2026; manuscript dated 20 Apr 2026; repo wrapped up ~7 May 2026. Two analytical arms: depth/missingness and PCA. Conclusion: archaic pigmentation prediction is not yet well-supported → caution. Full artifact-by-artifact inventory was produced separately (project inventory dossier).